Intelligent Data Ingestion
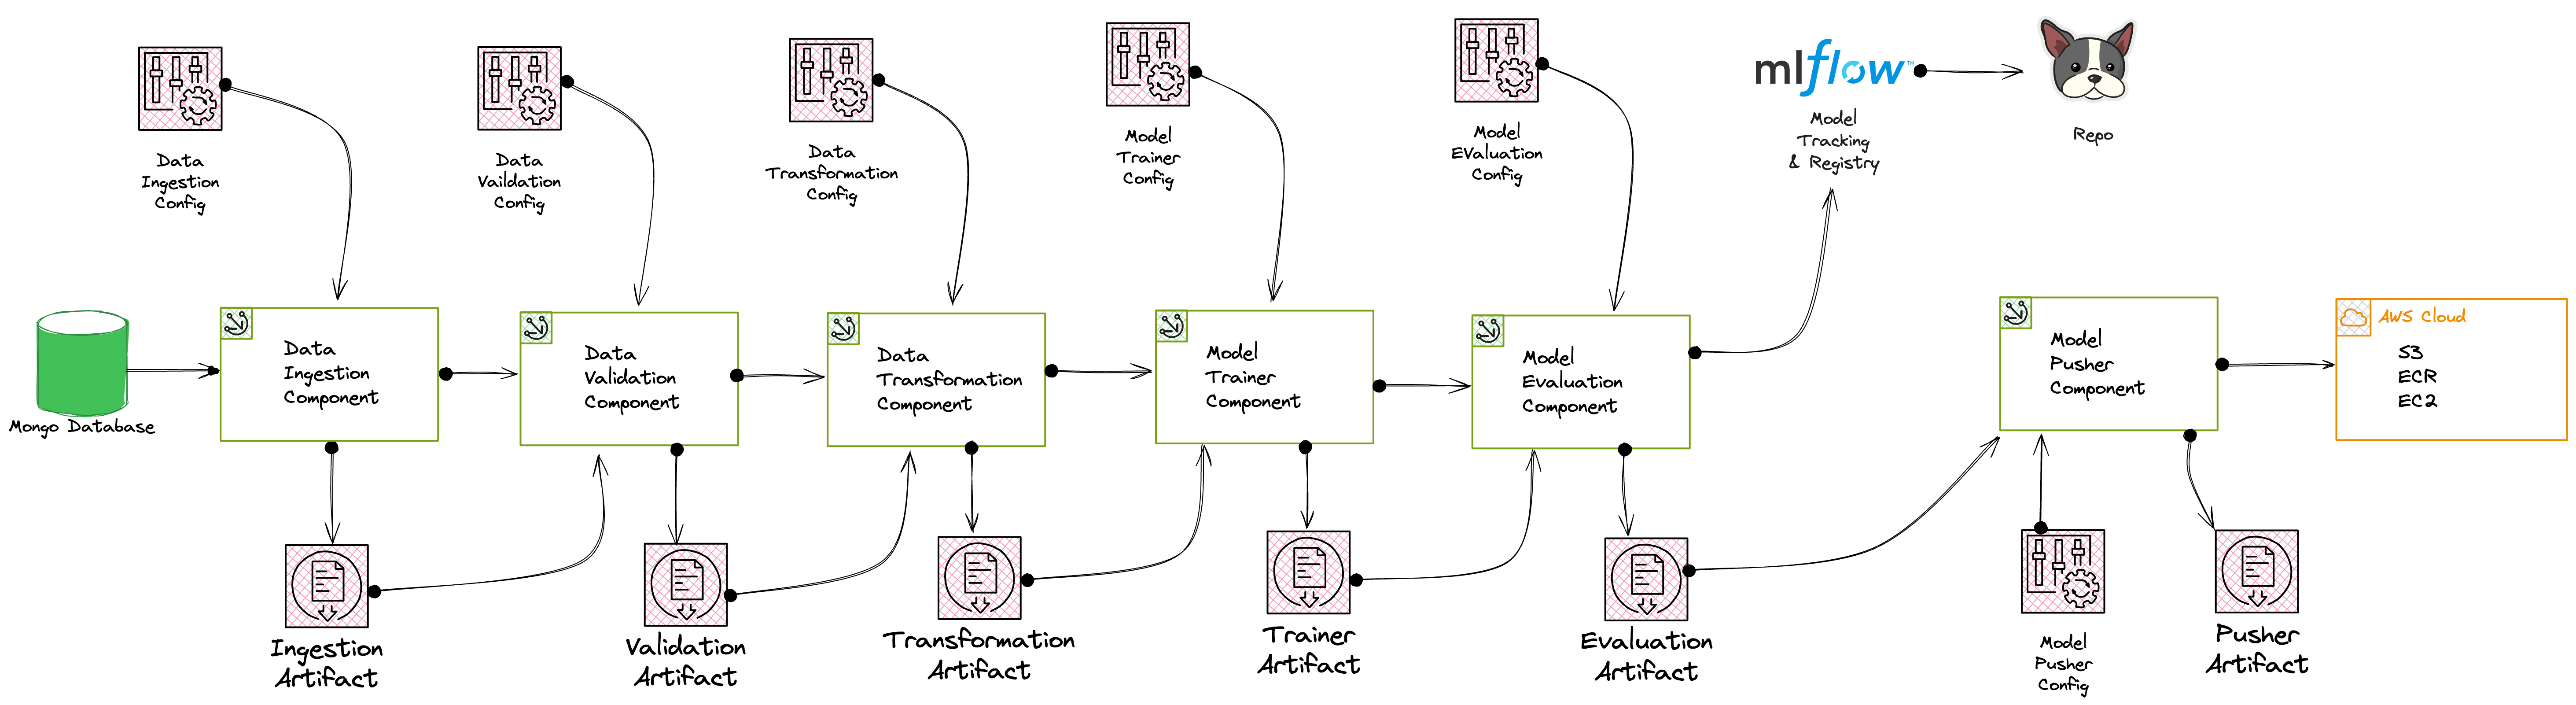
Automated data collection from multiple sources with real-time validation. The pipeline extracts 30+ URL and website attributes, ensuring data quality and consistency for downstream ML models.
Sophisticated feature engineering pipeline that transforms raw URL data into meaningful signals. Includes domain analysis, SSL certificate validation, and behavioral pattern detection.
Trained multiple ML models including Random Forest, XGBoost, and Gradient Boosting. Ensemble approach combines predictions for robust phishing detection with minimal false positives.
Deployed on AWS using S3 for data storage, ECR for container registry, and EC2 for compute. Docker containerization ensures reproducibility and MLflow tracks experiments and model versions.
Production-ready inference API with real-time monitoring and alerting. Scalable architecture handles high-throughput requests while maintaining low latency and high availability.
Live System Demo

Architecture/Flow